9 min read · AI pilots · AI strategy
Is it true that 95% of AI pilots fail?
Capio team
Short answer: not exactly. The viral line comes from a July 2025 MIT study that defined success as marked and sustained P&L impact. We explain what it really measured and how to design pilots you can judge.
Not exactly. The viral line traces to a July 2025 preliminary study from Project NANDA at the MIT Media Lab. In that report, “success” meant marked and sustained productivity or P&L impact reported by users or executives. Under that strict bar, roughly five percent of task specific enterprise tools in the sample reached “successful implementation” in the period studied, and the rest did not show measurable financial impact under that definition. That is not the same as saying almost all pilots never work or never ship.
Some headlines simplified the nuance and overstated the sample. A Fortune newsletter popularised “95 percent of pilots are failing,” but the methodology it quoted conflicts with the PDF’s own counts. Always read the primary source. The PDF and links to it are here: The GenAI Divide: State of AI in Business 2025 and the headline that amplified it is here: Fortune newsletter.
For context beyond one study, S&P Global’s 451 Research reported rising abandonment before production, but nothing like ninety five percent: the share of companies abandoning most AI initiatives before production rose to 42 percent year over year, with an average 46 percent of proof of concept projects scrapped before production. Source: S&P Global Market Intelligence, 30 May 2025.
What does the ninety five percent claim actually refer to?
It refers to a narrow success definition in one study. Project NANDA’s report defined a “successful implementation” as one with marked and sustained productivity or P&L impact, as reported by users or executives, in the period they studied. Under that definition, only a small share of task specific tools cleared the bar.
What did the MIT Project NANDA study measure and how did it define success?
The team combined a review of 300 plus initiatives, 52 organisation interviews and 153 senior leader surveys at four conferences during January to June 2025. Success for task specific tools meant “marked and sustained” productivity or P&L impact. See the PDF and its executive summary and methods sections: MIT Project NANDA, July 2025.
What does no measurable P&L impact mean in practice?
It means the organisations in scope did not report a clear and sustained improvement on a business metric that finance would recognise during the study period. It does not mean the pilot never worked or will never work. It means it did not cross a high evidential bar in time.
Did the MIT report say ninety five percent of pilots fail?
No. The PDF shows a funnel for task specific enterprise tools: about 60 percent of organisations evaluated a product, about 20 percent piloted one, and about 5 percent reached “successful implementation” under the definition above. It also notes that general purpose LLM chatbots saw high pilot to implementation rates, around 83 percent, but that is not a P&L result. Source: MIT Project NANDA PDF.
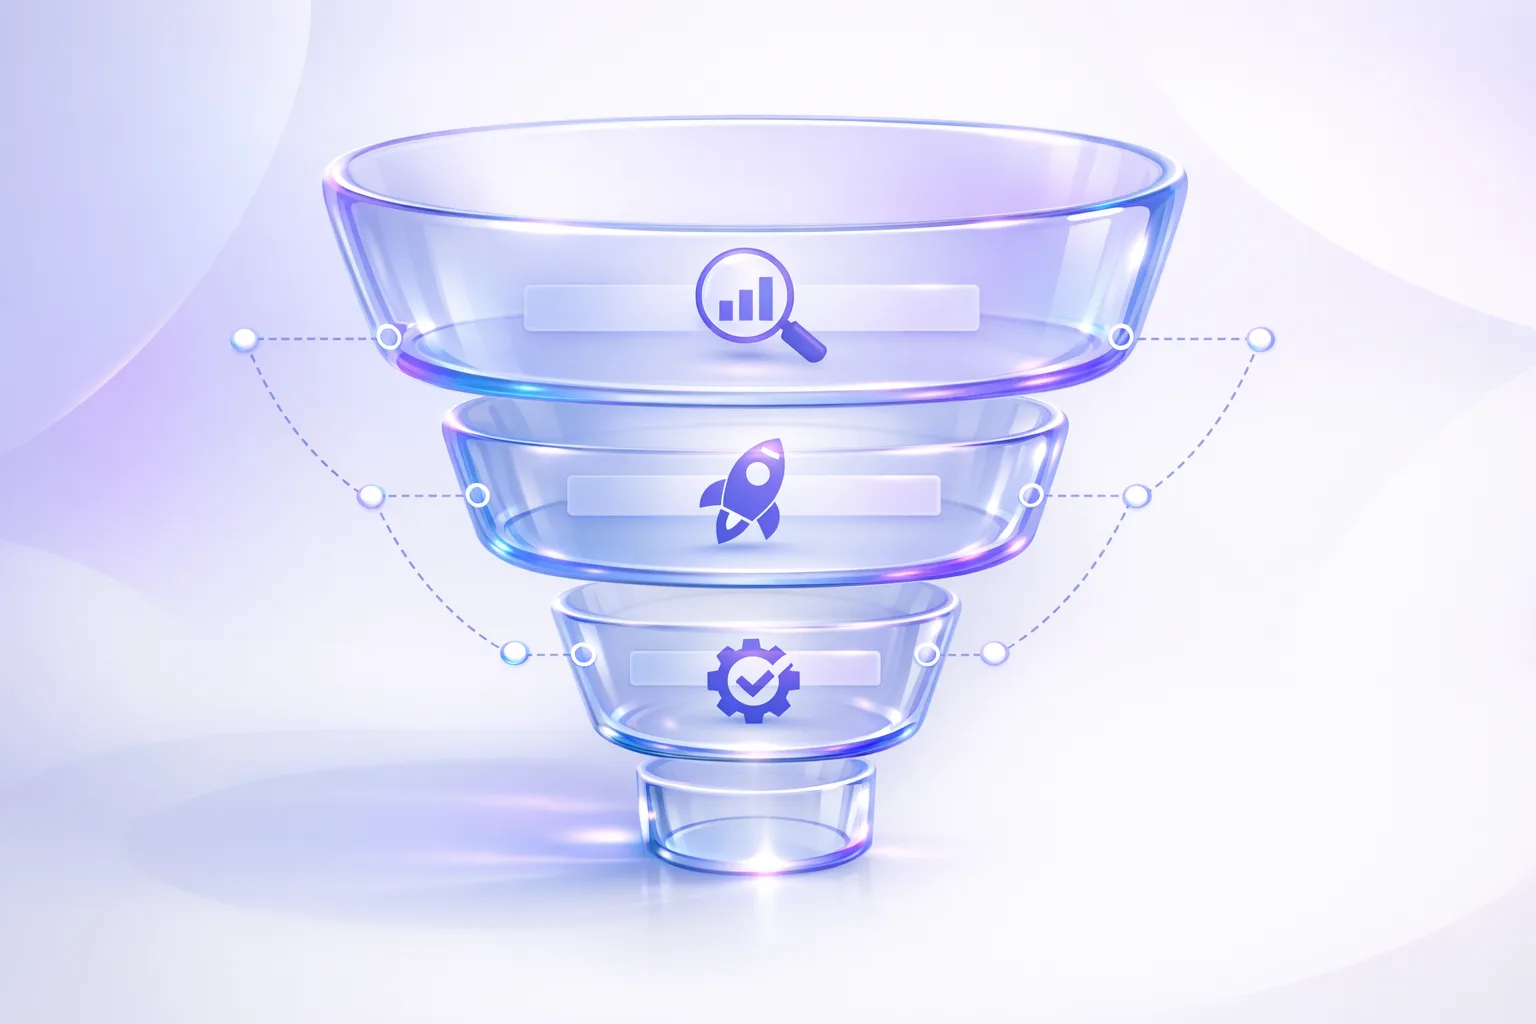
What the report’s funnel shows
It shows a classic attrition curve. Many organisations evaluate, fewer run a pilot, and fewer still both reach production and show marked and sustained impact. The last step is the strict one.
How reaches production differs from produces measurable financial impact
Reaching production means the thing is live in a workflow. Producing measurable P&L impact means it is live and moving a finance accepted metric by a meaningful, sustained amount in the period you observe. The latter is a higher bar.
What do other datasets say about pilots reaching production or being abandoned?
S&P Global’s 451 Research found abandonment before production is common and rising, but not near ninety five percent. Their May 2025 highlights cite 42 percent of companies abandoning most AI initiatives before production and an average 46 percent of proofs of concept scrapped before production. Source: S&P Global Market Intelligence.
What did S&P Global’s 451 Research find about abandoned proofs of concept?
The summary states the average share of proofs of concept scrapped before production was 46 percent, and the proportion of companies abandoning most initiatives before production rose to 42 percent year over year. That describes production attrition, not ROI.
How should leaders read conflicting figures without overgeneralising?
- Check definitions. “Pilot,” “production” and “measurable P&L impact” are not interchangeable.
- Check the time window. A short window penalises slower value realisation.
- Check the method. The Fortune newsletter quoted larger samples than the PDF describes. Compare headlines to the primary PDF and the Fortune piece.
So, is the statement that ninety five percent of AI pilots fail correct?
Not as a blanket claim. A safer wording is:
- You can quote: “A July 2025 preliminary report from Project NANDA at the MIT Media Lab found that about 95 percent of the organisations it studied reported no marked and sustained productivity or P&L impact from their generative AI initiatives in the period observed, and that roughly 5 percent of task specific tools in its sample reached successful implementation under that definition.” Source: MIT Project NANDA PDF.
When boards hear “ninety five percent of pilots fail,” they can misread it as “nothing works.” The study measures a high bar, over a short window, in a specific sample. Treat it as a caution to design for value, not as a verdict against AI.
Why do AI pilots stall before production or fail to show measurable value?
Most stalls are organisational, not algorithmic. In practice the recurring blockers are simple to name and hard to fix.
- Automating a broken workflow rather than redesigning it first.
- No empowered owner. Without decision rights across data, process and tech, a pilot drifts.
- Chasing visible use cases over value pools. Demo friendly front office bets often lose to back office economics.
- Measuring activity not outcomes. “Usage hours” is not a CFO metric.
- Integration debt. Without data, identity and controls, even a strong PoC cannot run in anger.
Buy vs build, with evidence and caveats
The MIT study observed that deployments reached production more often when organisations partnered with vendors than when they built internally, roughly 67 percent versus 33 percent in its sample. The authors note limits and correlation, not causation. Use it as a prompt to check your posture, not a rule. Source: MIT Project NANDA PDF.
How should you design a pilot you can judge quickly?
Build for a decision, not a demo. Set up the pilot so a sponsor can say scale, iterate or stop on evidence they trust.
Who owns it and what authority do they need?
Name one accountable owner with authority over scope, data access, workflow change and go live. Give them a steering forum that can make trade offs in real time.
One outcome metric, baseline and workflow mapping before any build
Pick a single outcome that finance signs off, baseline it, and instrument the workflow so you can attribute changes to the pilot. Map the steps and data handoffs before you touch a model.
The delivery gates and what each one proves
- Proof of concept proves the core technique can achieve the target outcome on representative data.
- Minimum viable product proves the end to end workflow with human in the loop and controls.
- Enterprise solution proves reliability at scale and hands ownership to the line team.
How do you measure measurable P&L impact credibly?
Use CFO grade metrics and transparent methods.
- Choose a business metric finance already tracks. Examples include unit cost, cycle time or revenue per case.
- Set a clear baseline window that reflects recent operations and seasonality.
- Where possible, run a controlled comparison, such as before versus after with the same team, or A and B cohorts.
- Attribute value conservatively in shared workflows. If AI claims part of a win, show the split and the chain of cause.
- Write a one page readout that shows the metric movement, the causal path, the risks and controls, the cost to scale and the decision request.
What should you stop doing to avoid joining the ninety five percent?
- Stop betting only on attention grabbing use cases. Hunt back office pools where a small lift pays the bills.
- Stop shipping PoCs without a baseline and a metric the CFO signs.
- Stop automating bad processes. Fix the flow, then apply AI.
- Stop running without an empowered owner.
- Stop counting activity as impact. Outcomes win.
How does CAPIO PRO approach AI pilots so they reach production?
We run pilots through three gates with clear owners, metrics and readouts.
- Proof of concept, two to six weeks. We test whether the approach can hit the agreed outcome on representative data. Why: it avoids wasting months on an idea that cannot work.
- Minimum viable product, one to three months. We build the end to end workflow with human in the loop, controls and measurement. Why: it proves the work as it will actually run.
- Enterprise solution, owned by your team. We harden, scale and hand over. Why: value only appears when the line owns and runs it.
Each pilot is scoped to a single business outcome with an agreed success metric. We measure against a baseline and make a scale or stop decision at each gate. This sits inside an AI operating system with a structured steering rhythm, and we use a readiness assessment to baseline leadership, governance, data, technology, capability, measurement and trust before heavy bets.
Frequently asked questions
Are external partnerships always better than internal builds?
No. The MIT study observed higher deployment rates in its sample for external partnerships than internal builds, but it cautions that this is correlation, not causation. Use partnerships to go faster where the capability is mature, and build in house where the capability is strategic and the scope is tight. Source: MIT Project NANDA PDF.
How long should I give a pilot before deciding?
Set the decision date at the start. A proof of concept should be short, an MVP should be long enough to observe stable operations, and the enterprise step is a scale and handover. The key is not the calendar, it is whether you can measure the outcome credibly at each gate.
What is a fair way to attribute value in a shared workflow?
Agree the chain of cause and share the credit. If AI reduces handling time that lets the team process more cases, split the effect between the model and the process change, and show both in the readout.
How do I prevent shadow AI from undermining governance while learning from it?
Stand up lightweight guardrails and an intake path. Publish what is allowed, add a fast track to bring promising shadow use cases into the inventory, and put human in the loop and data controls in place as you formalise them to strengthen governance.
Where to start
Pick one workflow with a clear owner and a single outcome metric finance already trusts. Baseline it, then run a proof of concept that can earn its way to the next gate on evidence.